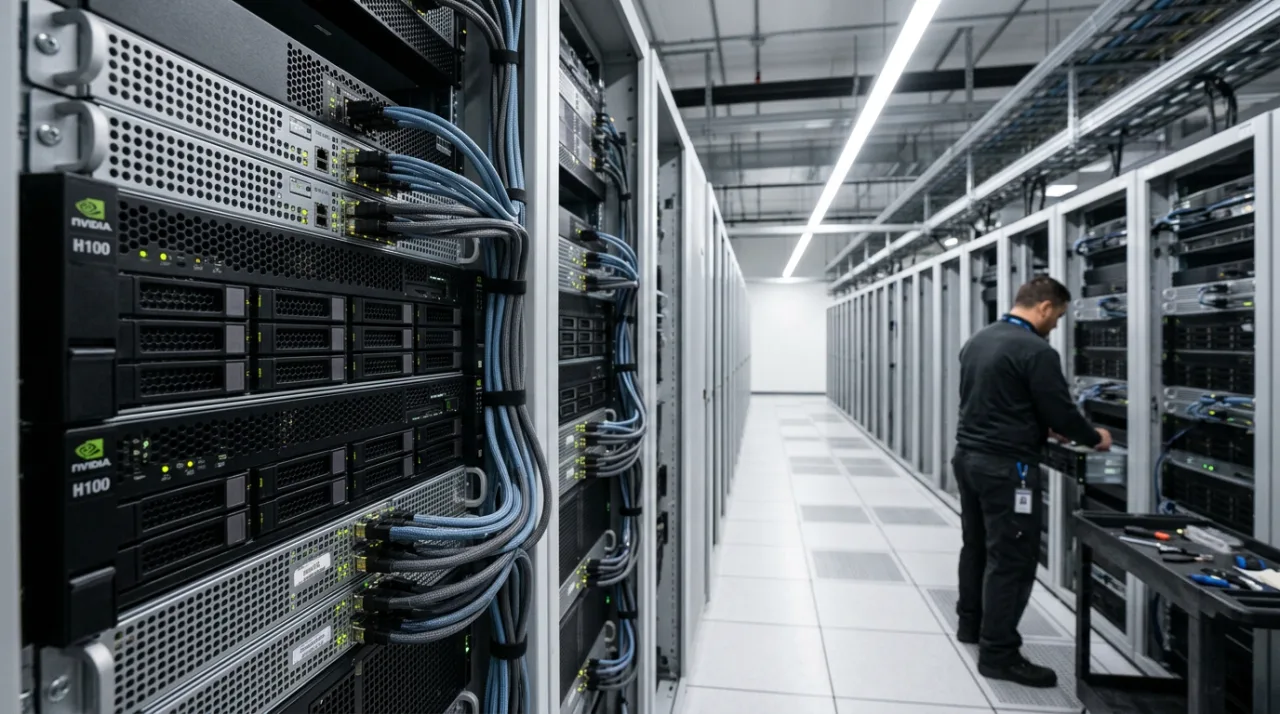
Mistral AI released Mistral Large 4, nicknamed Le Chonk, on October 29, 2026. The roughly 1-trillion-parameter natively multimodal Mixture-of-Experts model ships with open weights after a three-week public preview that began October 6.
Mistral Le Chonk Architecture and Performance Metrics
The model contains approximately 1.05 trillion total parameters with 49 to 52 billion active per token across 128 routed experts. It supports a 1-million-token context window and accepts text plus image inputs while producing text outputs through a 1.6-billion-parameter vision encoder. Training occurred from scratch on 3,800 to 4,000 NVIDIA Grace Blackwell GPUs in European data centers, and the model handles more than 160 languages including all official EU languages.
Three reasoning modes allow users to balance cost and output quality, with the high mode set as default. On coding benchmarks the model records 48 percent on the Artificial Analysis Coding Agent Index while consuming 47 percent fewer tokens than the previous leader. Terminal-Bench 4.0 scores reached 41 percent after reinforcement learning improvements, up from 28 percent at preview. Cybersecurity performance stands at 51 percent on the Artificial Analysis Cyber Index with a 96.6 percent refusal rate on malicious prompts.
Availability extends to Hugging Face under the mistralai/Mistral-Large-4-1T-A52B variants in FP8 and NVFP4 precision, the Mistral API and Studio, OpenRouter, and NVIDIA endpoints. Compatible inference frameworks include vLLM, SGLang, Transformers, and llama.cpp. API pricing after release lists $0.70 per million input tokens, $0.07 per million cached input tokens, and $2.10 per million output tokens.
License Terms and Enterprise Deployment Options
The Mistral Ecosystem Open-Weight License permits free use, modification, fine-tuning, and commercialization inside internal systems or customer products. Model-as-a-Service hosting requires a separate commercial license from Mistral. The company positions the release for defensive applications such as vulnerability discovery, reproduction, validation, and patching. Partners including CrowdStrike, Cloudflare, Rubrik, Zscaler, Booz Allen, Orange Cyberdefense, and ENISA participated in testing.
Mistral emphasizes sovereign AI principles through European training infrastructure and on-premises or private-cloud deployment options. The model trails certain Chinese open-weight systems on aggregate intelligence indices yet leads or ties on several agentic coding tasks. Human preference evaluations rate it above multiple Chinese competitors in direct comparisons.
Future Development and Integration Roadmap
Mistral reports that reinforcement learning gains continue without saturation and plans further updates to guardrails for both API and future versions. Specialized variants for vetted partners will address specific cybersecurity workflows. Mistral Large 5 remains in pretraining while the current model receives ongoing ecosystem support from Elastic and NVIDIA through Mistral Forge customization tools.
Independent benchmark verification continues. Enterprises evaluating open-weight models for internal coding agents or defensive security tooling can download weights immediately from Hugging Face and test against existing closed models on their own infrastructure.
Frequently asked questions
What benchmarks does Mistral Le Chonk lead?
The model leads or ties on several agentic coding benchmarks including 48 percent on the Artificial Analysis Coding Agent Index and 41 percent on Terminal-Bench 4.0 after post-preview reinforcement learning.
Can organizations host Mistral Le Chonk themselves?
Yes, weights are available under the Mistral Ecosystem Open-Weight License for internal use and product integration. Model-as-a-Service hosting requires a separate commercial license.
How does Mistral Le Chonk handle malicious prompts?
The model achieves a 96.6 percent refusal rate on malicious cyber prompts during testing with partners including CrowdStrike and Cloudflare.
What is the current API price for Mistral Le Chonk?
API pricing stands at $0.70 per million input tokens, $0.07 per million cached input tokens, and $2.10 per million output tokens.
By YasTech Editorial
Comments 4