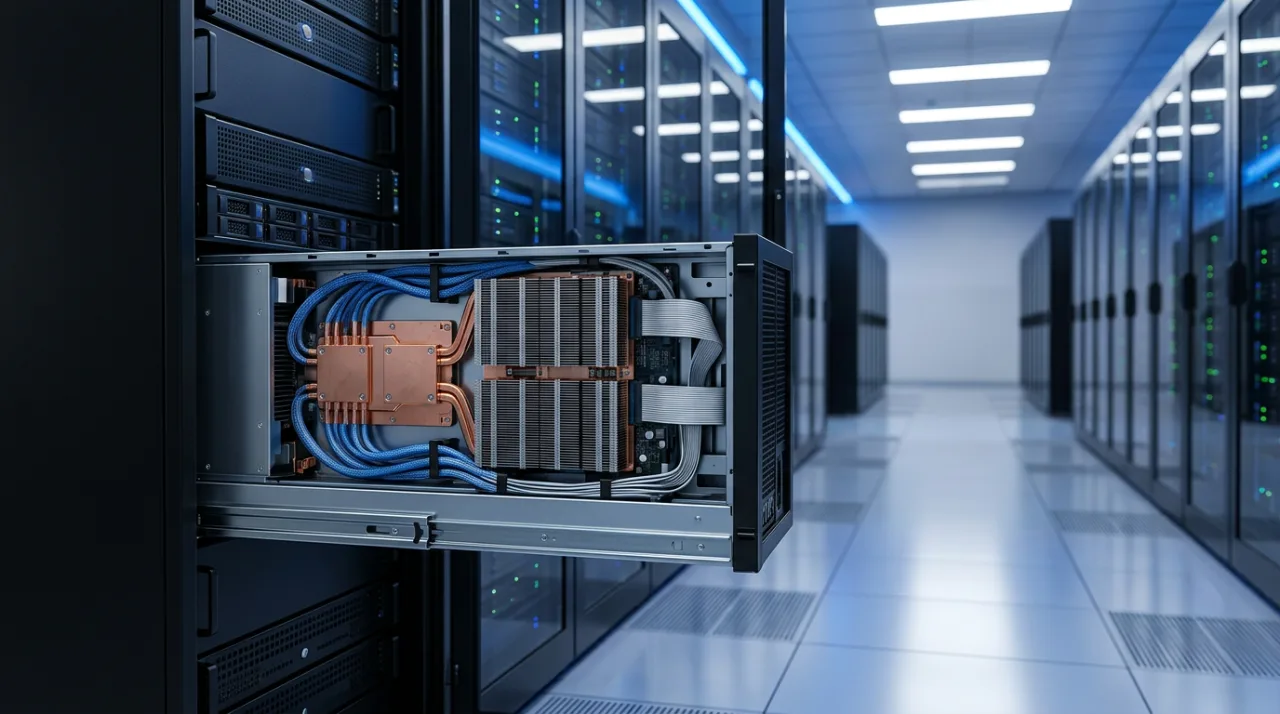
Microsoft announced the Azure Maia 300 on October 12, 2026, at the OCP Global Summit. The third-generation custom inference accelerator follows the Maia 100 from 2023 and the Maia 200 introduced in January 2026. Production deployments begin in 2027 at multi-gigawatt scale, positioning the chip family as the primary inference system across Microsoft products and services.
Microsoft Maia 300 Specifications and Architecture
The Maia 300 uses a multi-chiplet design on TSMC N2P process for compute dies, with separate dies for memory controllers and I/O. Each accelerator carries a 950W TDP rating and eight HBM4 stacks that provide 288 GB capacity at 18 TB/s peak bandwidth. Peak compute reaches 13.8 POPS in FP4 and 6.9 POPS in FP8. The card connects through a PCIe Gen6 x16 interface and supplies 3.2 TB/s bidirectional scale-up bandwidth plus 32 ports of 400Gb/s Ethernet.
A full rack holds 96 accelerators in a liquid-cooled 167 kW envelope across 24 trays. This configuration yields 27.6 TB total HBM capacity and 1.7 PB/s aggregate bandwidth. Superpods can scale to 12,288 accelerators through a two-tier Ethernet network with custom AI transport. The architecture incorporates software-defined dataflow, locality-aware NUMA memory, and reduced-precision formats such as MXFP4 to support long-context reasoning and agentic workloads.
Microsoft positions the chip for latency-sensitive conversational AI and multi-step tasks. It builds on the Maia 200, already deployed in the United States, Europe, and Australia for workloads including Microsoft Copilot, GitHub Copilot, and OpenAI models. The new design increases on-die SRAM and optimizes data movement to improve efficiency in these areas.
Performance Claims and Comparison to Maia 200
Microsoft states the Maia 300 delivers up to 7x rack-scale token throughput compared with a full Maia 200 rack. It also claims more than 2.5x performance per watt, 2.5x HBM bandwidth, 33% more HBM capacity, 2x HBM bandwidth per watt, 36% more system compute FLOPs, and 14% more scale-up bandwidth versus the prior generation. The company expects 40% more tokens per megawatt than leading GPU-based systems, though workload specifics remain unspecified.
These figures position the accelerator for inference at scale rather than training. Nvidia and AMD GPUs continue to handle training workloads, while the Maia family focuses on cost and power efficiency for deployed models. Scott Guthrie, EVP of Cloud and AI, noted that the family will scale to multi-gigawatt deployments from 2027 onward. Satya Nadella described the effort as the company’s largest commitment to its own silicon.
Further technical details will appear at Microsoft Ignite in November 2026 in San Francisco. Actual rollout speed will depend on TSMC wafer supply and integration with existing GPU clusters. Early Maia 200 deployments already reported up to 1.7x tokens-per-watt gains versus GPU infrastructure on selected Copilot features, providing a baseline for the projected improvements.
Deployment Timeline and Practical Implications for Azure Customers
Microsoft plans to make the Maia 300 the default inference platform for its own services and for customers using Azure AI Foundry and Microsoft MAI models. Organizations running long-context agents or conversational workloads can expect lower per-token costs once capacity becomes available. The liquid-cooled rack design requires data centers equipped for high-density liquid cooling, which may limit initial availability to Microsoft’s own facilities.
Enterprises evaluating Azure for inference should monitor capacity announcements after the 2027 ramp. The shift reduces reliance on external GPU suppliers for inference but leaves training on established Nvidia and AMD hardware. Integration timelines will determine when specific model families gain access to the new accelerators.
Frequently asked questions
When will the Microsoft Maia 300 enter production?
Production deployments are scheduled to begin in 2027. Microsoft plans multi-gigawatt scale across its data centers, making the chip the primary inference system for its products and services.
How does the Maia 300 compare to the Maia 200 in efficiency?
Microsoft claims more than 2.5x performance per watt and up to 7x rack-scale token throughput versus the Maia 200. HBM bandwidth rises by 2.5x while capacity increases 33 percent.
What workloads benefit most from the Maia 300 architecture?
The chip targets long-context reasoning, latency-sensitive conversational AI, and multi-step agentic tasks. Features such as software-defined dataflow and locality-aware memory support these use cases.
Will the Maia 300 replace Nvidia GPUs in Azure?
No. The accelerator focuses on inference workloads. Nvidia and AMD GPUs remain central for training, while the Maia family handles deployed inference at lower power per token.
By YasTech Editorial
Comments 1